New Delhi [India], October 19: The government has approved 190 projects under the IndiaAI Mission and committed ₹10,372 crore to the ecosystem around them. Forty-six sit with startups and MSMEs, and thirty more with early-stage startups. Every one needs recorded Indian material to train on, and most of it has never been collected.
The models the mission has already delivered include text-to-speech in Bengali, Gujarati, Kannada, and Malayalam, which is the half of the problem that speaks. Compute was the expensive problem. Data is the slow one.
Where the funding meets the recording gap
A model carries the market it was recorded in. Trained on quiet rooms and one language per sentence, it meets India and misses:
- A support call that names the merchant in English, the installment in Marathi, and the amount in Hindi.
- A kirana shelf stacked with regional packaging no global dataset has ever photographed.
- A handwritten ledger in a script the model has never been shown.
- A pack label in Malayalam, sitting next to one in Hindi.
Boards are asking for AI results, and technical teams are already building. This is the wall they hit, and the cost is countable: repeat calls, escalations to a human, and a pilot that never leaves the demo.
On request, not off the shelf
Two things trade under the one name:
- Off the shelf. A finished file, assembled once and sold to whoever buys it next.
- On request. Recorded in a written brief, in named districts, by people paid to supply it.
Off-the-shelf files were assembled for someone else’s brief. Projects that need named districts and languages need the second kind.
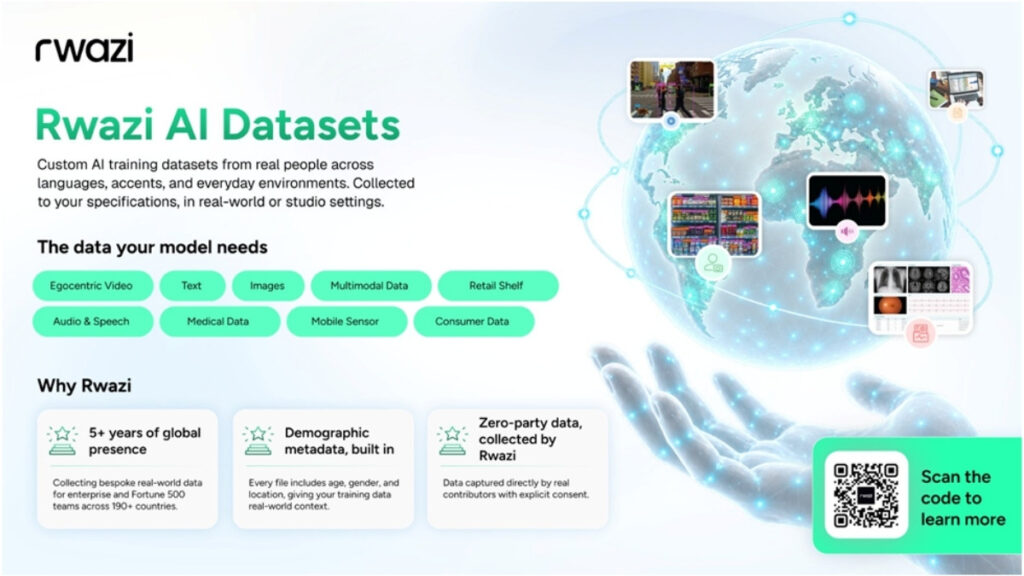
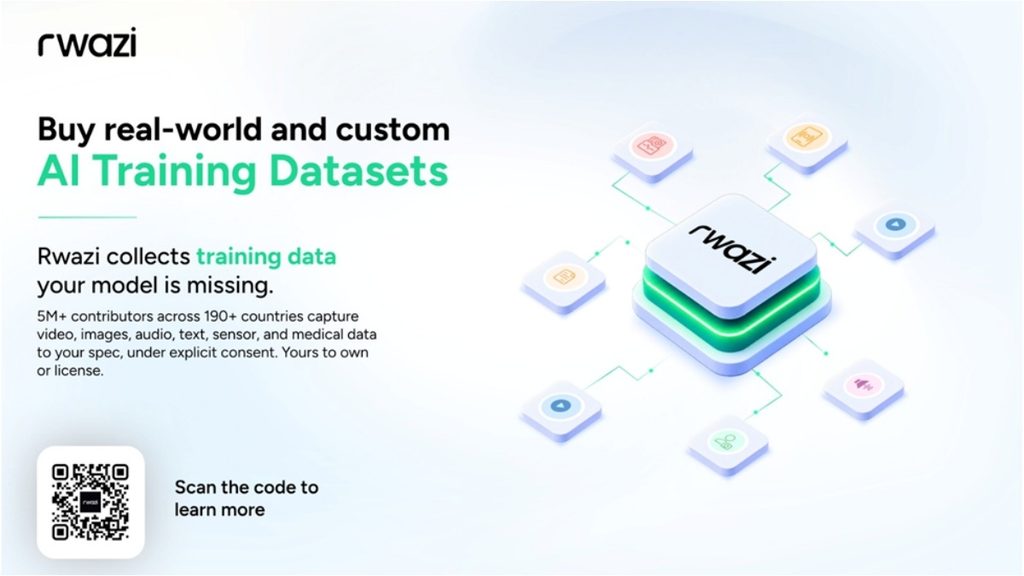
That is the work Rwazi does. Rwazi collects real-world AI training data on request, project by project, through a network of real people across 190+ countries who agreed to share what they record. The same network is how an Indian team reaches a market outside India without rebuilding collection for it.
All nine types, collected on request
One Indian project usually crosses several of these, and a single brief can carry all nine.
- Audio and speech. Support calls and read speech with transcripts. Text-to-speech Hindi is solved; a voice bot that listens across accents and code-mixed sentences still needs a speech dataset recorded here.
- Video. A video dataset shot rather than scraped, including first-person capture for robotics.
- Image. An image dataset captured on request. Most computer vision projects in India stall here: packaging, signage, storefronts, and handwriting.
- Text. Written in the Indian language in the script people actually use, mixed-script included.
- Mobile sensor. Location, motion, and device signals contributed from handsets at district resolution.
- Multimodal data. Two or more recorded together and aligned, for models that read context.
- Consumer data. What people bought, where, and what they chose instead, below the metro boundary.
- Retail shelf. Shelf photography from real stores for pricing, availability, and planogram work.
- Medical. Packaging, labels, and pack imagery, where medical AI in India runs shortest.
Send a brief, and get recorded data back
Before any contract is signed:
- What to send. Type, languages, districts, volume, and date. Or the single line that matters most: what the model keeps getting wrong and where.
- What comes back. A sample recorded by contributors in the markets the brief names, not an extract from a catalogue.
- What it costs. No fee for the sample, and no agreement is signed first.
- Where it goes. Rwazi’s AI datasets team.
How the data collection runs
- Agreement. A master service agreement and a statement of work lock the brief.
- Samples. Recorded against it and checked before anything scales.
- Scale. Raw phone capture and studio-grade capture run on the same rails, so one project can ask for both.
Nothing is inferred. Every recording is supplied by the person who made it.
“A model that fails in a district town fails for everyone who lives there,” said Joseph Rutakangwa, CEO, Rwazi. “The recording has to happen where the customer is, in the language the customer uses.”
What this decides
India’s AI money is already committed. The 190 approved projects will be judged on whether their models work in the districts their customers live in, rather than in a demonstration, and that comes down to what was recorded, in which languages, and under which conditions. The computer arrived first. The data decides what it produces.